Code is notthe product.

Agents now write code faster than anyone can read it. Onus is the layer every coding agent works through. It reads each change for what it means, routes it by risk, and approves it on evidence.

v0.11.0 · Open source, Apache-2.0 · One binary for macOS, Linux and Windows

Output scales. Attention doesn't.

A careful reviewer covers about 400 lines in one sitting.1 When one company pushed to double merged pull requests, output did double, and review couldn't keep up. Human review fell from 89% to 68% of pull requests.2

More pull requests
3.1×
More reviewers
1.5×

Growth after the push to double output.2

Signal from noise.

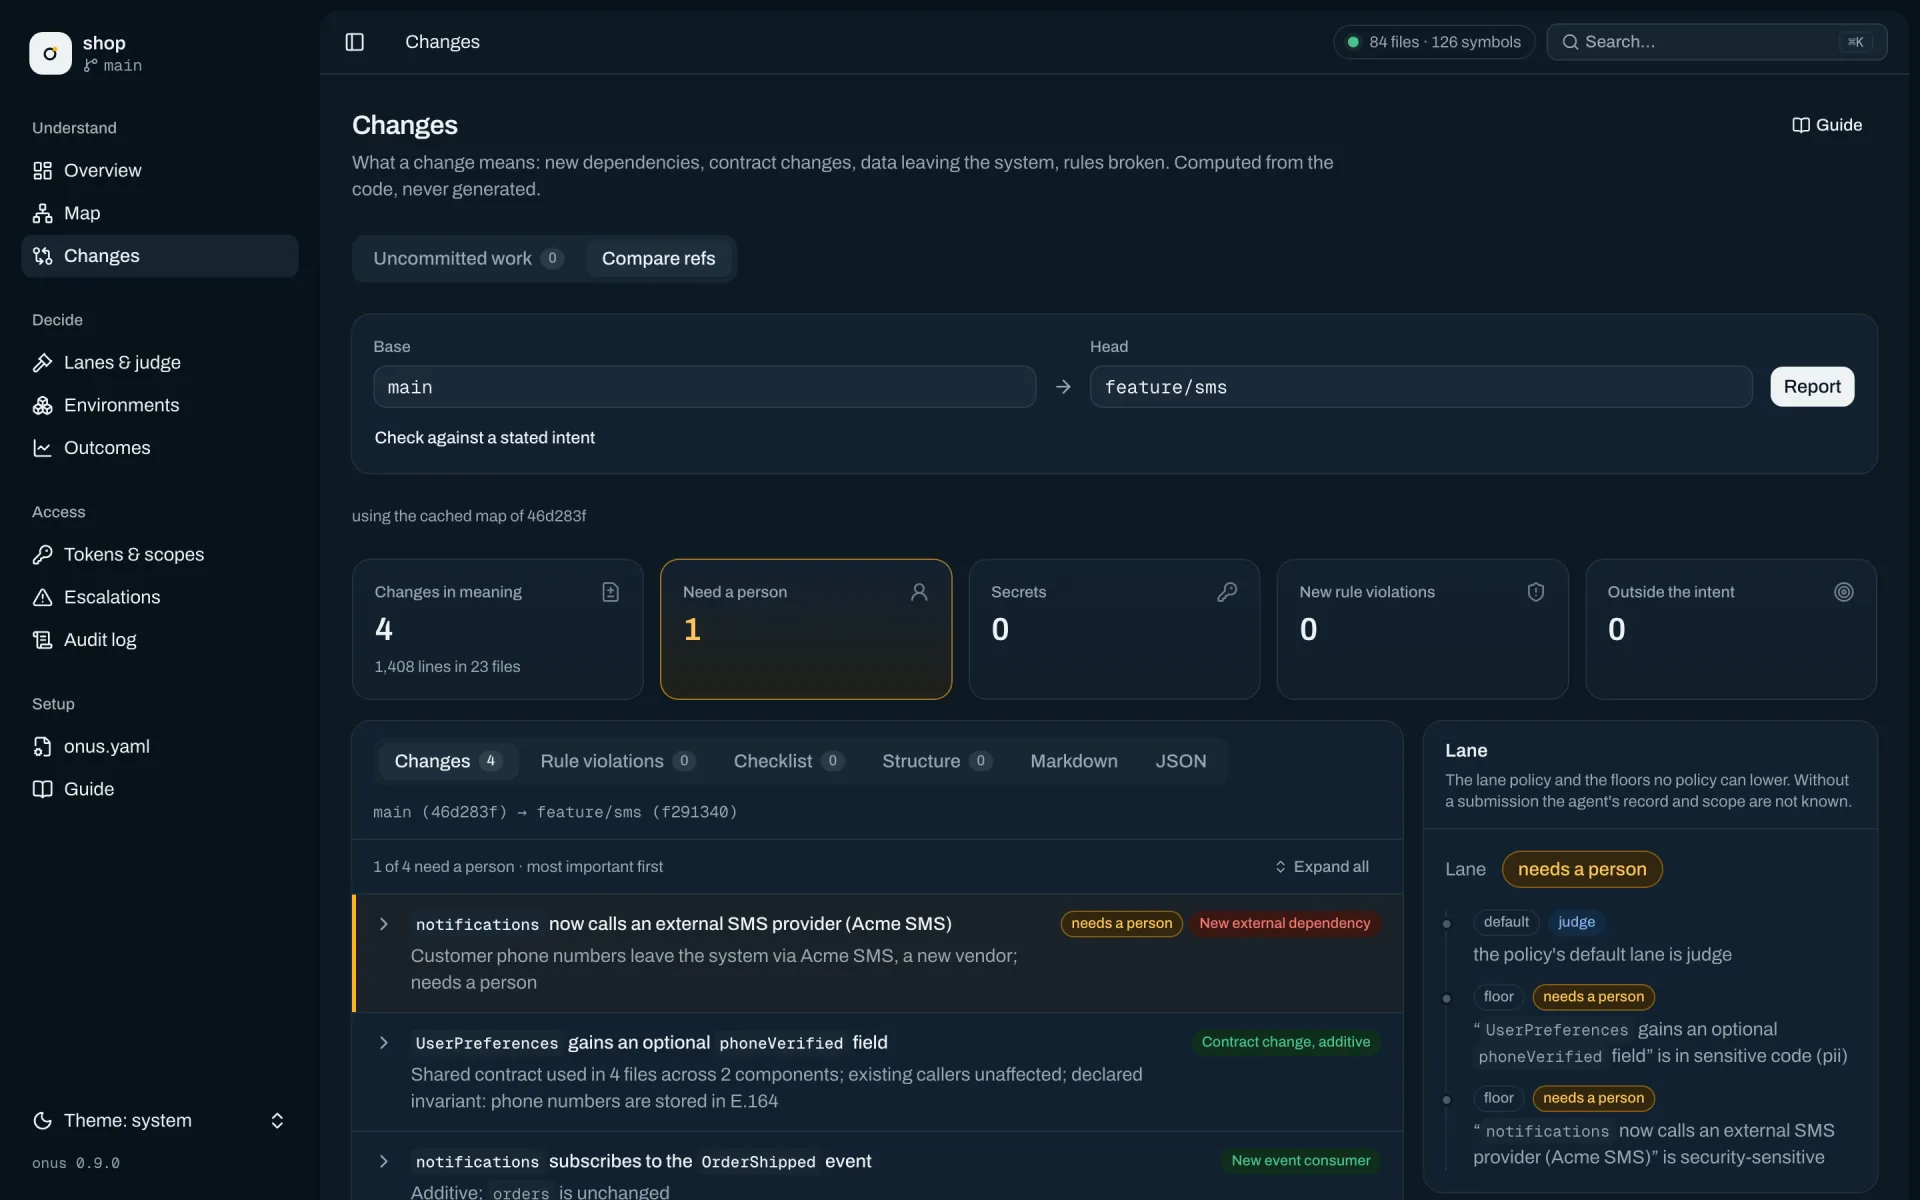
Onus reads a change the way a reviewer wishes they could: as a few shifts in meaning, most important first. 1,450 changed lines become four rows. One needs a person.

  • notifications now calls an external SMS providerNew external dependencyCustomer phone numbers leave the system
  • UserPreferences gains an optional phoneVerified fieldContract change, additiveShared contract; existing callers unaffected
  • notifications subscribes to the OrderShipped eventNew event consumerAdditive; orders itself is unchanged
  • About 1,400 lines of new code and tests inside notificationsInternalNo other component touched

Real pull requests, read.

Four merged pull requests from Twenty, an open-source CRM with 31,000 TypeScript files. These are Onus's reports, row for row, with long file lists shortened. Nothing in the repository was run.

twentyhq/twenty#27430

Inbox: chat subscriptions and server-side mentions

+1,711 −337 in 68 files→13 rows, 3 for a person

  • ● STANDARD_OBJECT_FIELDS changes its agentChatThreadParticipant valueContract change, unverifiedShared contract used in 14 files across 4 components; Onus cannot prove the change is compatible, so it is treated as breaking
  • ● New migration 2-46-workspace-command-…-add-agent-chat-thread-subscriptions.command.tsMigrationIt changes stored data: deploy it before code that relies on the new shape, and check it can be rolled back
  • ● New GraphQL mutations subscribeToAgentChatThread and unsubscribeFromAgentChatThreadPublic APINew public API: check who may call each operation and what it reads or writes
  • ○ Generated code changed in twenty-client-sdk (3 files, 56 changed lines)Generated codeWritten by a tool; review the schema or generator change it mirrors
  • ○ 878 changed lines of code and tests inside twenty-serverInternalStays inside twenty-server; no other component depends on it; adds 12 test cases

and 8 more quiet rows

Before the accuracy work, the migration and the two new mutations were buried in a changed-lines row. Now each one asks for a person.

How these were checked, and what is still weak: the report accuracy audit.

A live map, derived from code.

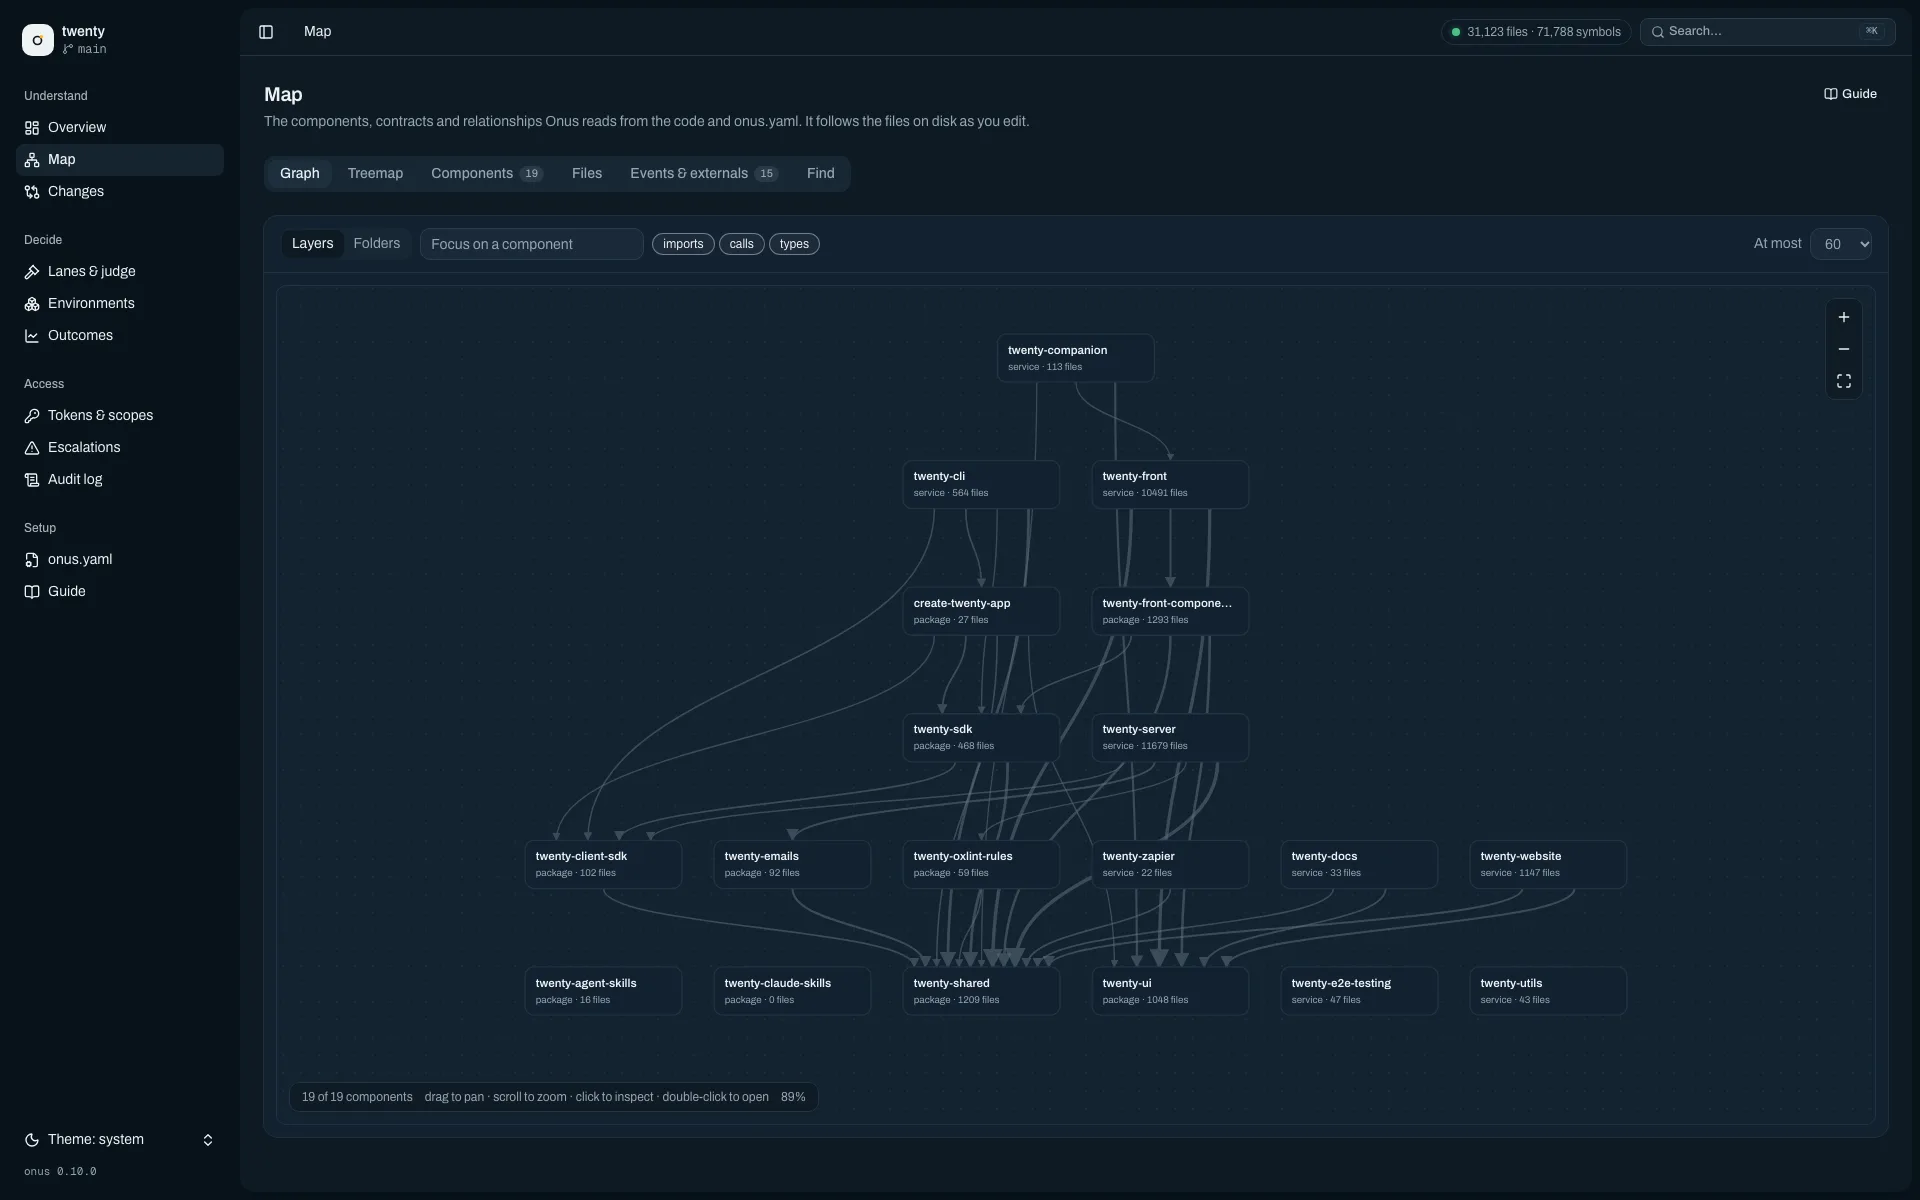
Components, contracts, owners and risk labels, rebuilt on every change. Agents ask the map instead of reading 50 files and guessing. This change adds one edge that matters: customer phone numbers now reach an outside SMS provider.

What depends on UserPreferences?notifications, billing

Twenty, an open-source CRM
31,000 files · 72,000 symbols
Mapped from scratch
3.5 s
A question to the warm map
under 1 ms
Dependents the compiler finds
99.9% found

Access is earned with proof.

Every task runs with a short-lived token that opens only the doors it needs. To get more, an agent attaches evidence, not a persuasive paragraph. A structured way to escalate cut test-gaming from 23.6% to 5.3% across eight frontier models.3

Token for “Text customers when their order ships”

Write
notifications internals
Read
OrderShipped, UserPreferences
Network
SMS provider test endpoint
Expires
When the task ends

Every change gets a lane.

Each change is routed by the rows of its report. Routine work merges on evidence alone, the judge takes the middle, risky changes go to a person, and some never merge as they are.

  • Auto-mergeWhat your rules allow, from an agent with 10 merged changes and no recent incidentDocs, by your ruleInternal changes your policy lists
  • JudgeThe default: verified on evidence before it mergesEverything no rule or floor moves
  • A personSensitive code, security and the rules of the gameAuth, payments, personal dataTests, CI and policyAnything outside the stated intent
  • BlockedUntil someone fixes it or approves itA committed secretWrites outside the task's scopeWeakened tests, unapproved

You write the rules in onus.yaml. Floors no rule can lower keep risky changes with people, and a learned model can only move a change up a lane, never down.

Agents apply. A judge verifies.

The judge re-derives the facts instead of giving an opinion. It never reads the author's reasoning, since models favor work that looks like their own.4

  • Re-runs the evidence in a fresh environmentThe author's test results are never reused
  • Compares intent to effectDoes the report match what the agent said it did?
  • Checks that no tests were weakenedDeleted assertions, skips, special-cased inputs
  • Runs checks the author never sawEspecially where features combine
  • Only then, judges tasteNaming and structure count, but less

Trust is earned, per agent.

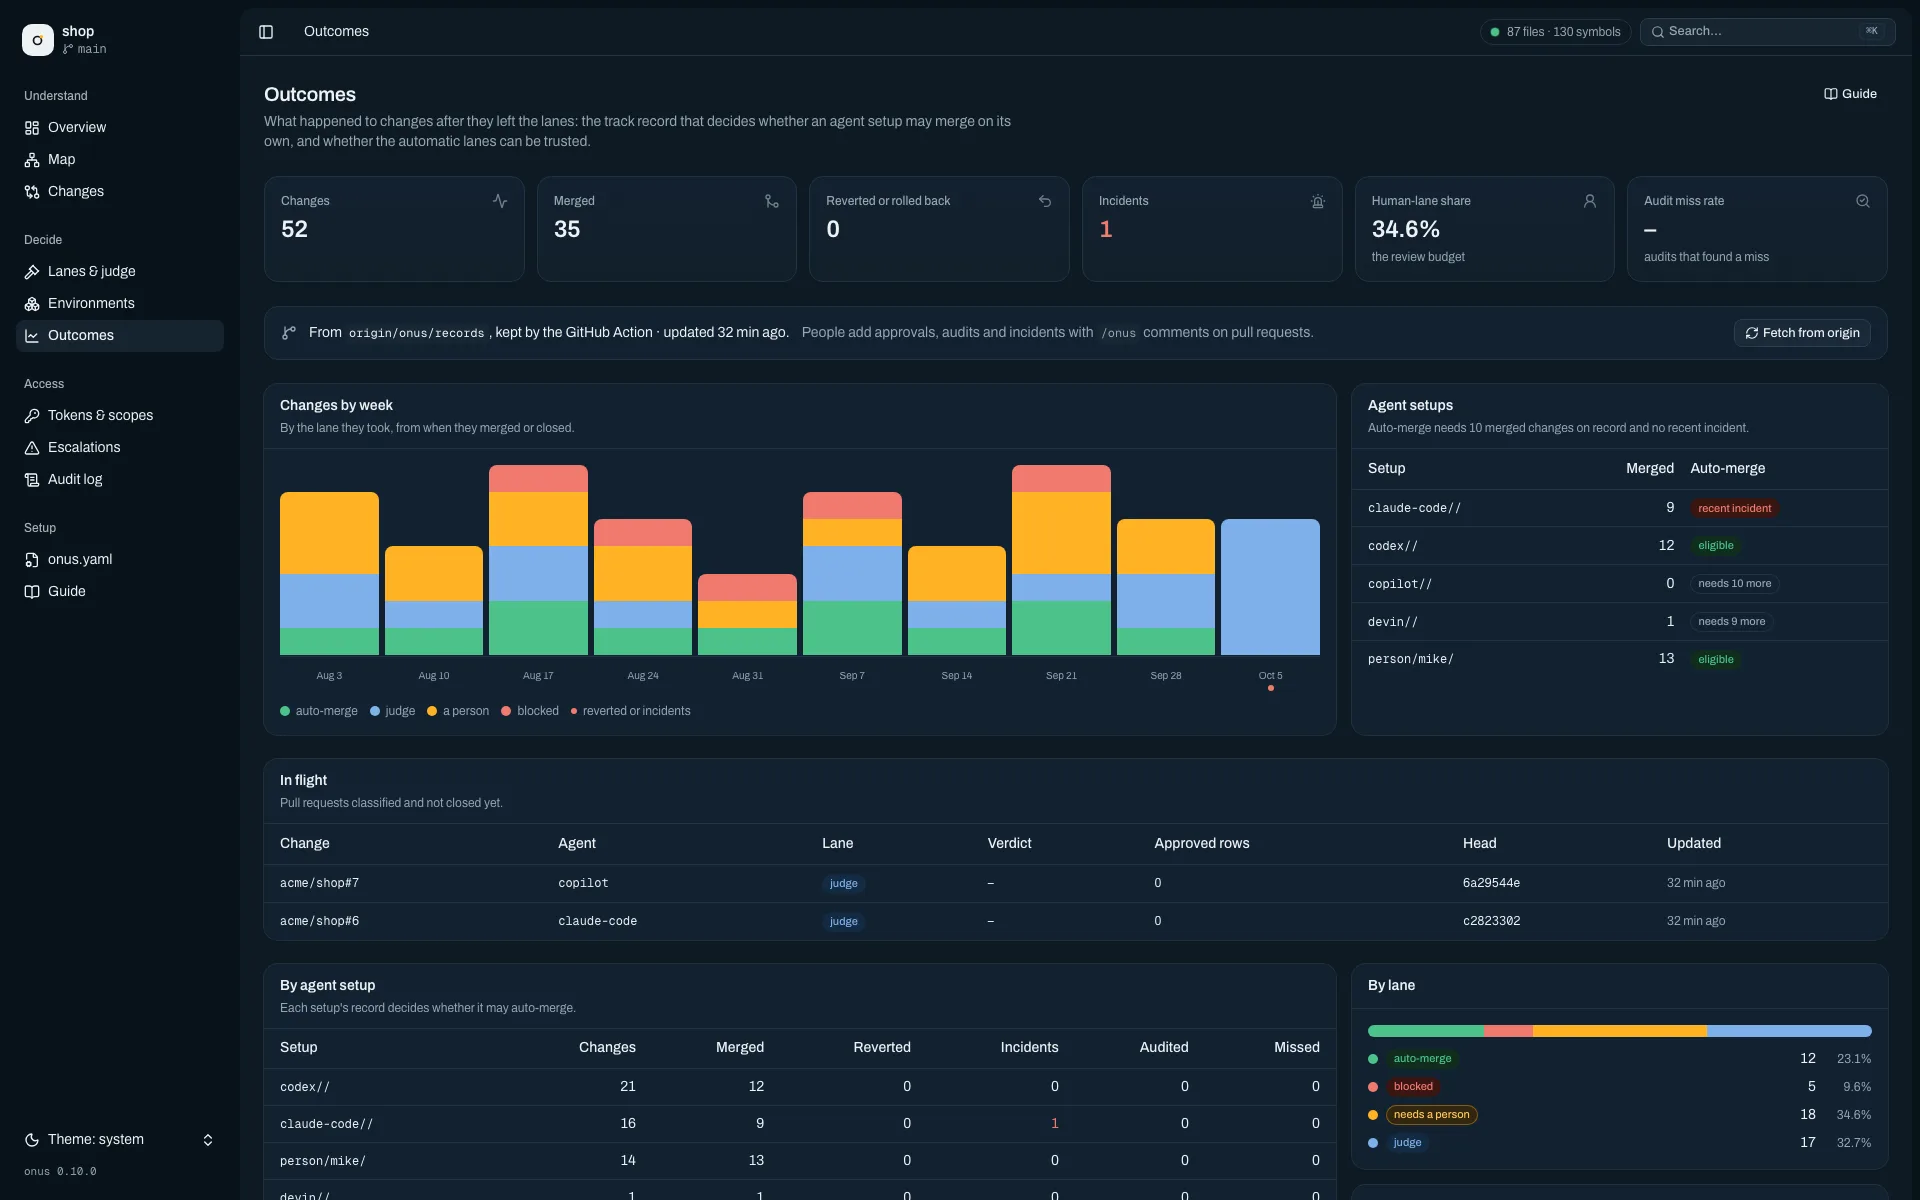
Every pull request leaves a record: which agent made it, the lane it took, whether it merged, and whether it was later reverted or caused an incident. CI keeps it on a branch of your repository. An agent setup may auto-merge only after 10 merged changes, and an incident among its last 20 takes that away until its record is clean again.

Agent setups

SetupMergedAuto-merge
codex12eligible
claude-code/opus9recent incident
devin4needs 6 more
person/maria31eligible
  • /onus approve new-external-service:external:acme-sms@notificationsa person approves one row; the lane updates
  • /onus audit miss the opt-out was ignoreda human audit of something that merged on its own
  • /onus incident SMS sent twice involved: notificationswhat broke, and where the next tests should go

People add what CI cannot see with a comment on the pull request; only people with write access are recorded. The agent is read from the branch name, the bot that opened it, or an Onus-Agent:trailer. Agents can never write their own record.

Any agent. Same rules.

Onus isn't an agent and doesn't pick one for you. Agents work through it over MCP, or a CLI if they can run a shell command. Each gets the same scopes, lanes and judge, and earns its own track record.

claude mcp add onus -- onus mcp# any MCP client: onus mcp
  1. Before it writes

    What a change would break, who uses it, and which tests cover it.

    onus_impactonus_dependentsonus_tests_foronus_invariants

  2. Before it finishes

    The changes in meaning of its own work, with a checklist of what to verify.

    onus_check

  3. To hand work in

    Tests run in an environment, a submission with that evidence, the judge's verdict.

    onus_env_runonus_submitonus_judge

  4. When it needs more

    Rights its token lacks, asked for with evidence and decided by policy or a person.

    onus_escalateonus_escalation

Agents cannot approve themselves: they cannot record outcomes, grant escalations, mint tokens or choose the scope they are checked against. Pull requests are attributed to Claude Code, Codex, Copilot, Cursor, Devin, Jules and Aider by their branch or bot, and to anything else by an Onus-Agent: trailer.

Swap every agent overnight and nothing in Onus changes. Only the track records start fresh.

All of it, in your browser.

onus ui opens the whole of Onus for the repository you are in. It ships inside the binary and serves on 127.0.0.1 behind a per-session token, so nothing is installed and nothing leaves your machine.

Measured, not claimed.

Measured on Twenty, an open-source TypeScript monorepo with 31,000 files, 72,000 symbols and 272,000 dependencies, on a laptop. Each method is published, including the results that went against us.

Is the map right?

Who depends on a symbol, against the compiler

Dependents the TypeScript compiler finds that Onus also finds
99.9%
Dependents Onus reports that the compiler confirms
92.3%

100 sampled symbols, 2,584 files. Most of the extra files are barrels that re-export a symbol: they break when it is renamed, though the compiler does not count them. Method of the references benchmark

Are the reports right?

20 large merged pull requests, audited row by row

First auditAfter fixes
Rows with a wrong fact7%under 1%
High-severity misses, in 20 pull requests91
Flag precision, 1 to 52.053.5
Usefulness, 1 to 52.13.0

Every kind of mistake found became a regression case that runs with the test suite. Method of the report audit

Is it fast?

On the 31,000-file repository

Map the whole repository
3.5 s
A question to the warm map
under 1 ms
The first question after an edit
2.0 s
Eight agents asking at once after an edit
1.7 s
A pull request report, base map cached
12 s

One map server per repository, shared by every agent and worktree; facts are cached by file content. Method of the speed figures

What didn't work

The map didn't make agents faster or better

In a blind A/B test on a real Twenty feature, agents with the map tools took 231 s and scored 7.5 of 10; without them, 235 s and 7.8. They explored with grep anyway. What they did use, unprompted, was onus_check before finishing. A second round with a sharper check did no better (6.3 against 8.0): a clean check read as “done”, so every answer now says what it does not verify. Onus puts its effort into checking work, not guiding it.

Claude Code with Sonnet, three runs per condition, graded blind against the shipped change. Method of the agent A/B test

Try it on your next pull request.

Everything on this page is in one binary. Reports only read files and send nothing anywhere; Onus runs your code only when you ask it to, in a container.

In a terminal

curl -fsSL https://onushq.com/install.sh | shonus report --base main --head HEADonus ui

macOS and Linux. Installs to ~/.local/bin after checking the SHA-256, or use Homebrew: brew install onushq/tap/onus. onus ui opens all of it in your browser. The guide is also built in: onus help.

On every pull request

permissions:  contents: read  pull-requests: write   # for the commentsteps:  - uses: actions/checkout@v7    with:      fetch-depth: 0  - uses: onushq/onus/action@v0.11.0    with:      fail-on: secrets

The GitHub Action posts the report as one comment, updated on each push, and fails the job only on what you list in fail-on. Add records: true and it also keeps each agent's track record (permissions and events).

Download

Each archive holds onus and the Svelte plugin, and carries a build attestation: gh attestation verify <archive> --repo onushq/onus.

We don't need people to read more code. We need a system where nobody has to pretend they did.

Onus comes from onus probandi, the burden of proof. Today it sits on a reviewer reading lines. Onus moves it to the agent, which has to show its work.